吉林大学学报(工学版) ›› 2026, Vol. 56 ›› Issue (10): 2648-2661.doi: 10.13229/j.cnki.jdxbgxb.20250498
• 计算机科学与技术 • 上一篇
基于多模态BEV特征融合的三维目标检测算法
才华1( ),孙微微1,张海峰2,张高鹏2,付强3,寇婷婷1,韩雨桐1
- 1.长春理工大学 电子信息工程学院,长春 130022
2.中国科学院西安光学精密机械研究所,西安 710119
3.长春理工大学 空间光电术研究所,长春 130022
Multi-modal Bird's Eye View (BEV) feature fusion for 3D object detection
Hua CAI1(),Wei-wei SUN1,Hai-feng ZHANG2,Gao-peng ZHANG2,Qiang FU3,Ting-ting KOU1,Yu-tong HAN1
- 1.School of Electronic and Information Engineering,Changchun University of Science and Technology,Changchun 130022,China
2.Xi'an Institute of Optics and Precision Mechanics,Chinese Academy of Sciences,Xi'an 710119,China
3.Research Institute of Space Optoelectronic Technology,Changchun University of Science and Technology,Changchun 130022,China
摘要:
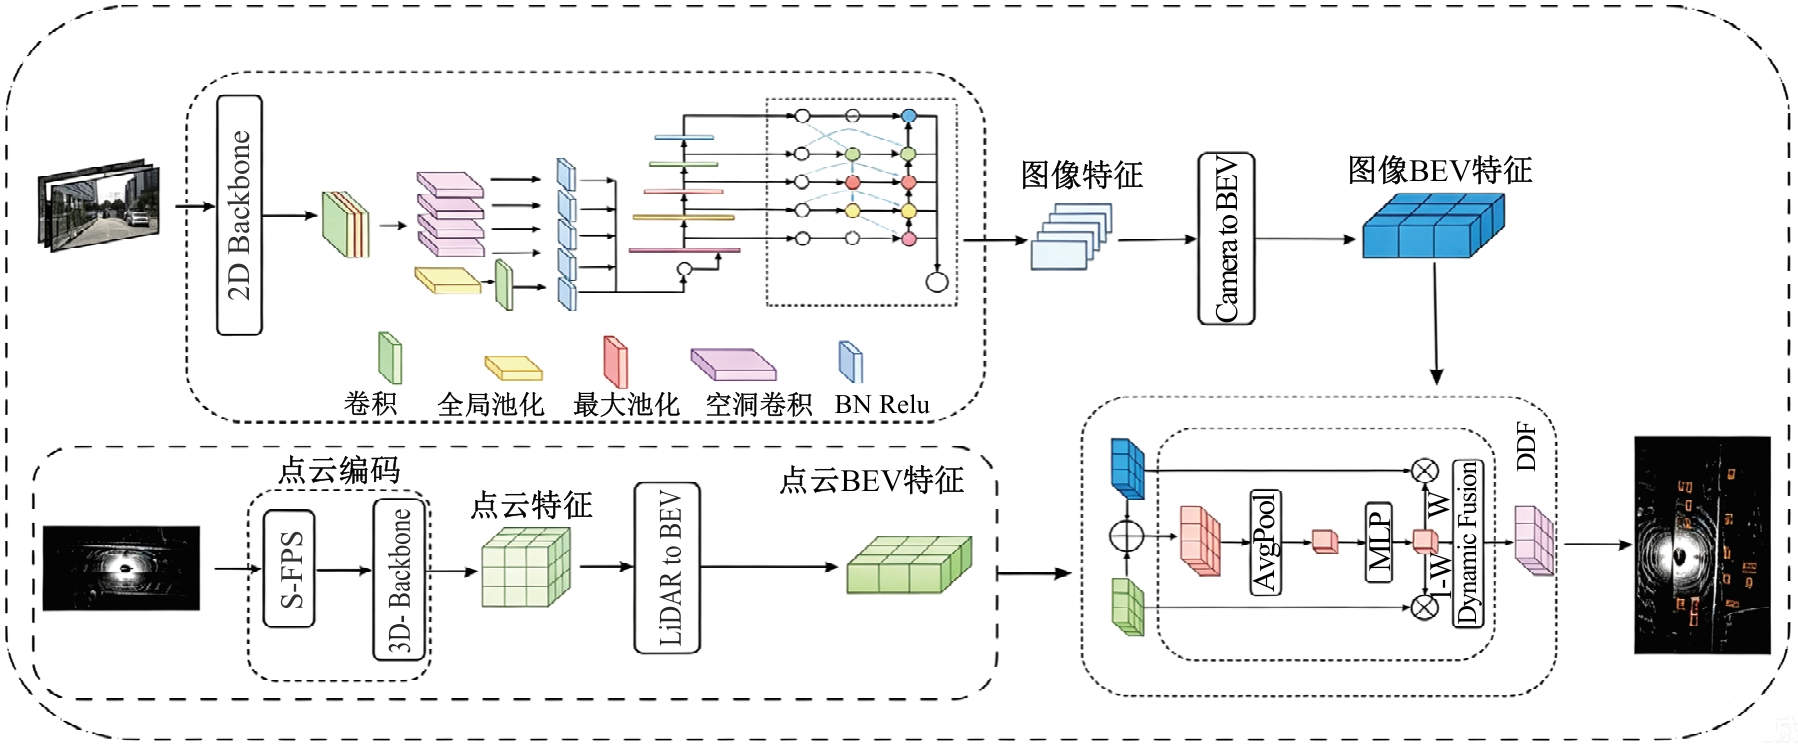
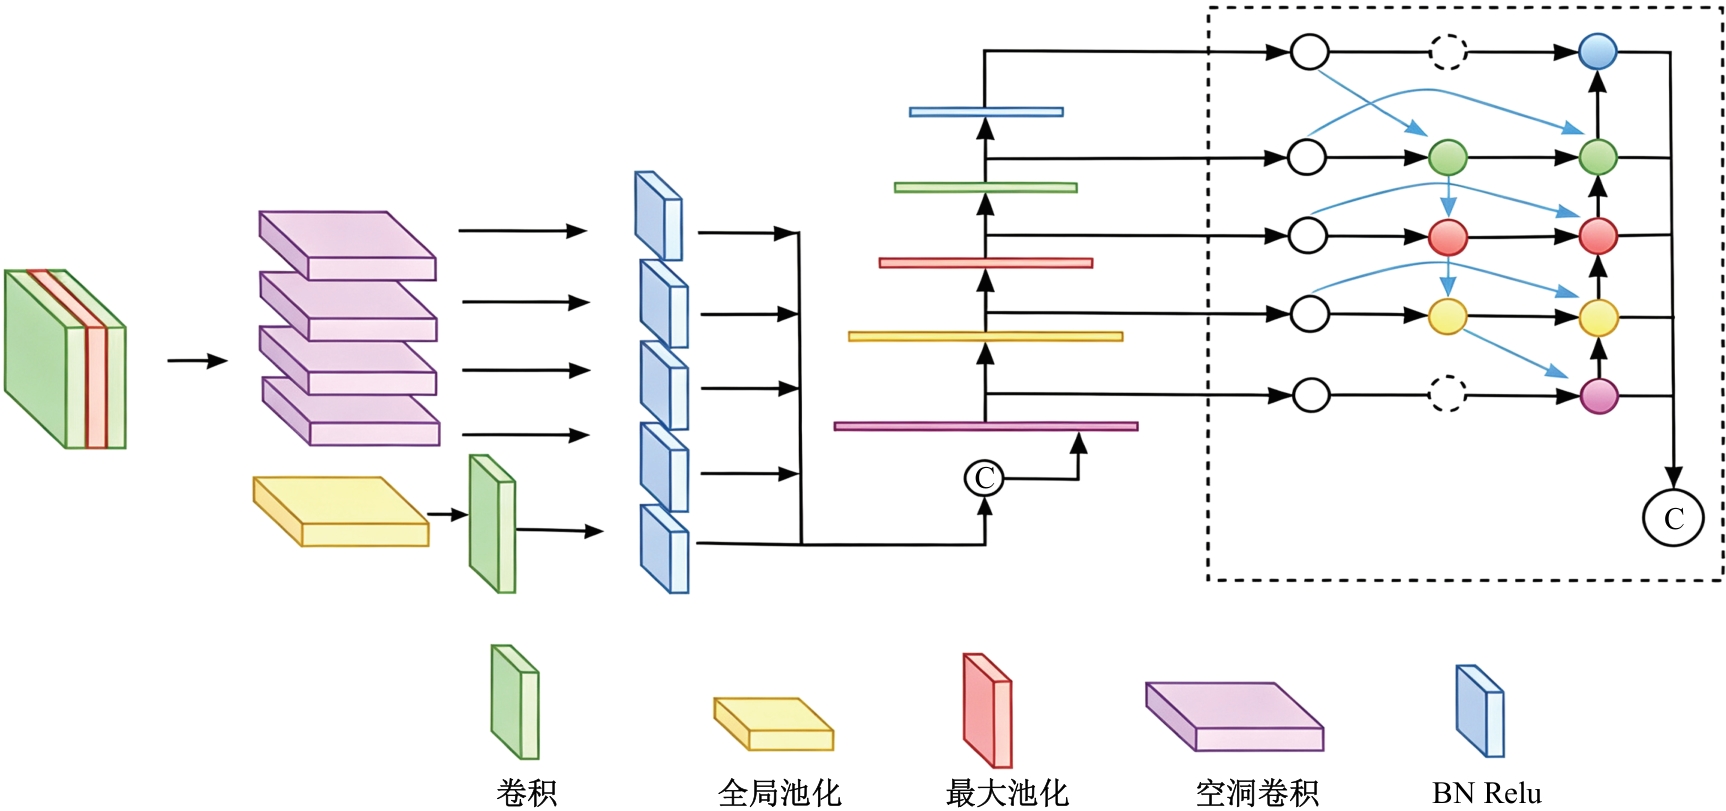
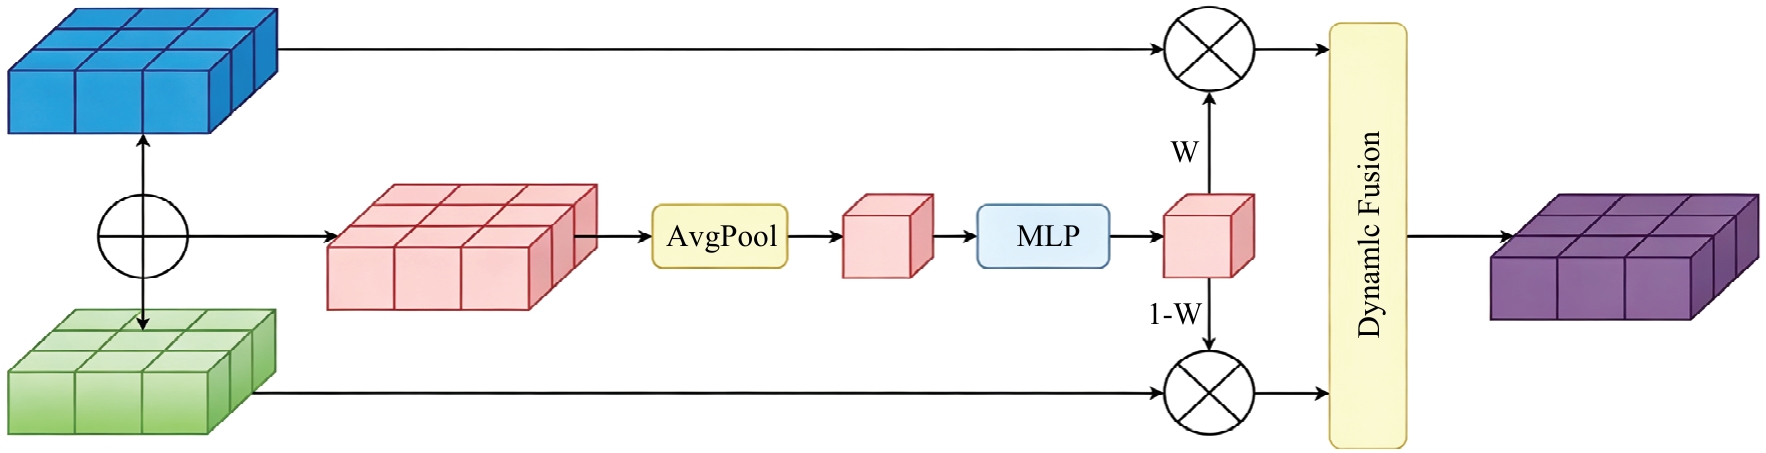
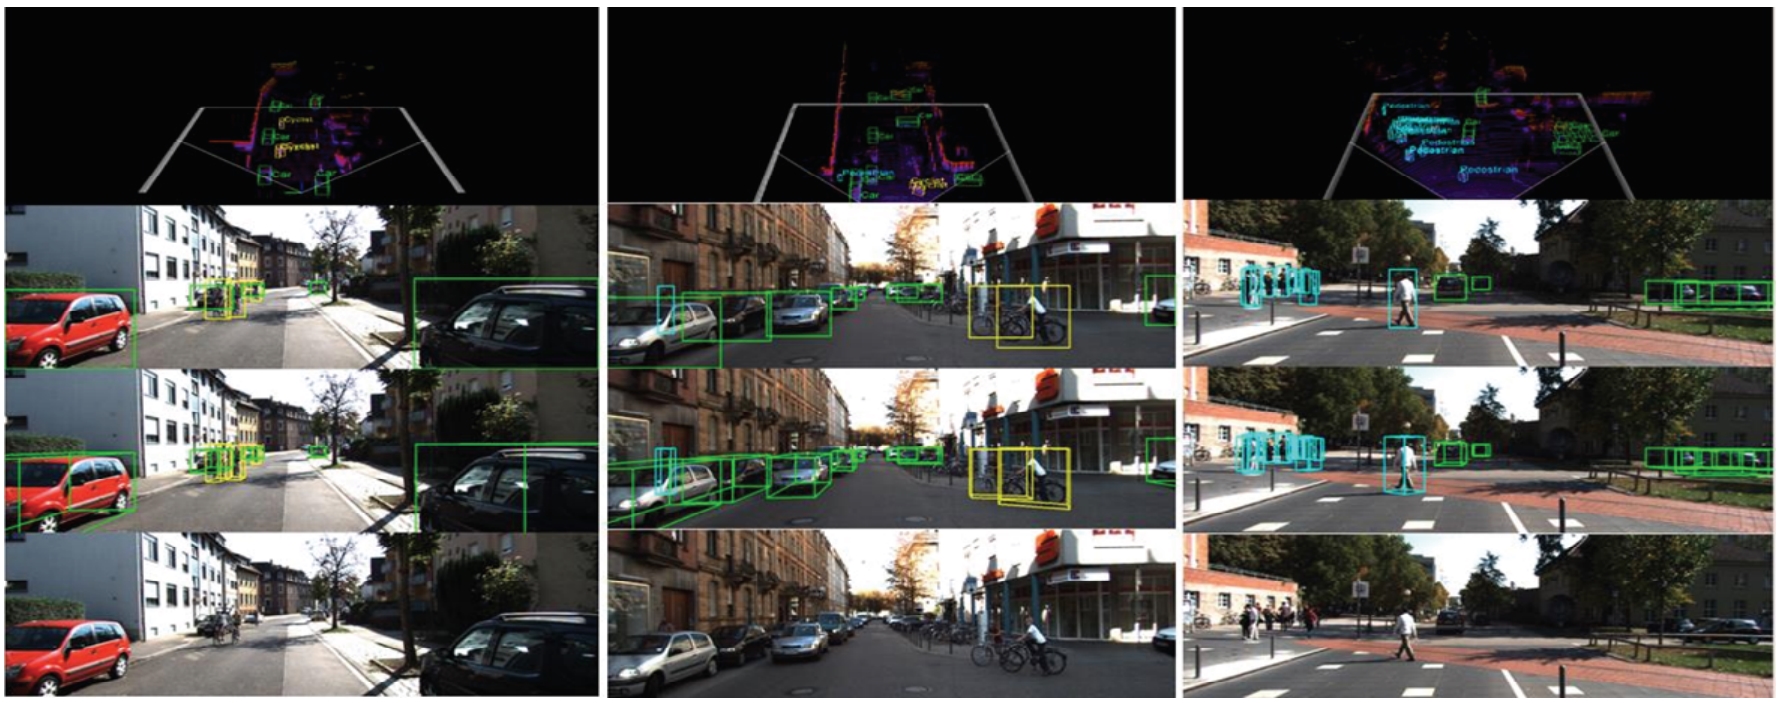
为了改善多传感器融合过程中图像局部语义信息丢失和关机键点采样过程中引入大量背景点的问题,提出了一种基于BEVFusion网络的改进算法,在图像流中引入空洞卷积和加权双向特征金字塔,扩张感知区域,维持语义完整性;引入语义感知的最远点采样算法,关注信息量更大的前景点;在动态融合网络基础上引入了挤压和激励操作,设计了自适应门控的双动态融合网络,动态地选择不同模态有价值的信息。本文使用KITTI 数据集进行实验评估,并在 nuScenes 数据集上进行了泛化实验。实验结果证明,本文算法与当前主流算法相比表现出更高的检测精度。
中图分类号:
- TP391

| [1] | Chen Y L, Liu S, Shen X Y, et al. DSGN: Deep stereo geometry network for 3D object detection[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA, 2020: 12533-12542. |
| [2] | Li P L, Chen X Z, Shen S J. Stereo R-CNN based 3D object detection for autonomous driving[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, USA, 2019: 7636-7644. |
| [3] | Sun J M, Chen L H, Xie Y M, et al. Disp R-CNN: Stereo 3D object detection via shape prior guided instance disparity estimation[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA, 2020: 10545-10554. |
| [4] | 才华, 郑延阳, 付强, 等. 基于多尺度候选融合与优化的三维目标检测算法[J]. 吉林大学学报: 工学版,2025, 55(2): 709-721. |
| Cai Hua, Zheng Yan-yang, Fu Qiang, et al. A 3D object detection algorithm based on multi-scale candidate fusion and optimization[J]. Journal of Jilin University(Engineering and Technology Edition), 2025, 55(2): 709-721. | |
| [5] | Meyer P G, Laddha A, Kee E, et al. LaserNet: an efficient probabilistic 3D object detector for autonomous driving[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, USA, 2019: 12669-12678. |
| [6] | Yin Z, Sun P, Zhang Y, et al. End-to-End multi-view fusion for 3D object detection in LiDAR point clouds[J]. Conference on Robot Learning,2019,100:923-932. |
| [7] | Wang Z X, Jia K. Frustum ConvNet: sliding frustums to aggregate local point-wise features for amodal 3D object detection[C]∥2019 IEEE/RSJ International Conference on Intelligent Robots and Systems, Macau, China, 2019:1742-1749. |
| [8] | Shin K, Kwon Y P, Tomizuka M. RoarNet: a robust 3D object detection based on region approximation refinement[C]∥IEEE Intelligent Vehicles Symposium, Paris, France 2019: 2510-2515. |
| [9] | Du X X, Ang M H, Karaman S, et al. A general pipeline for 3D detection of vehicles[C]∥IEEE International Conference on Robotics and Automation, Brisbane, Australia, 2018: 3194-3200. |
| [10] | Yoo J H, Kim Y, Kim J, et al. 3D-CVF: generating joint camera and LiDAR features using cross-view spatial feature fusion for 3D object detection[C]∥16th European Conference, Glasgow, UK, 2020: 720-736. |
| [11] | Zhang Y C, Guo Y, Niu H B, et al. SimpleFusion: 3D object detection by fusing RGB images and point clouds[C]∥International Conference on Pattern Recognition, Machine Vision and Intelligent Algorithms, Beihai, China, 2023: 47-51. |
| [12] | Bai X Y, Hu Z Y, Zhu X G, et al. TransFusion: Robust LiDAR-camera fusion for 3D object detection with transformers[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, USA,2022: 1080-1089. |
| [13] | Pang S, Morris D, Radha H. CLOCs: Camera-LiDAR object candidates fusion for 3D object detection[C]∥IEEE/RSJ International Conference on Intelligent Robots and Systems, Las Vegas, USA, 2020: 10386-10393. |
| [14] | Qi C R, Liu W, Wu C X, et al. Frustum pointNets for 3D object detection from RGB-D Data[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, USA, 2018: 918-927. |
| [15] | Liang T T, Xie H W, Yu K C, et al. BEVFusion: a simple and robust LiDAR-camera fusion framework[C]∥Proc IEEE Conf Comput Vis Pattern Recognit, 2022: 10421-10434. |
| [16] | Deng J J, Shi S S, Li P W, et al. Voxel R-CNN: towards high performance voxel-based 3D object detection[C]∥The Thirty-Fifth AAAI Conference on Artificial Intelligence, British Columbia, Canada,2021: 1201-1209. |
| [17] | Zhou Y, Tuzel O. VoxelNet: end-to-end learning for point cloud based 3D object detection[C]∥2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, USA, 2018: 4490-4499. |
| [18] | Yan Y, Mao Y X, Li B. SECOND: sparsely embedded convolutional detection[J]. Sensors, 2018, 18(10): 3337. |
| [19] | Shi S S, Guo C X, Jiang L, et al. PV-RCNN: point-voxel feature set abstraction for 3D object detection[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA,2020: 10526-10535. |
| [20] | Chen X Z, Ma H M, Wan J, et al. Multi-view 3D object detection network for autonomous driving[C]∥2017 IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, USA, 2017:6526-6534. |
| [21] | Ku J, Mozifian M, Lee J, et al. Joint 3D proposal generation and object detection from view aggregation[C]∥2018 IEEE/RSJ International Conference on Intelligent Robots and Systems, Madrid, Spain, 2018: 1-8. |
| [22] | Huang T T, Liu Z, Chen X W, et al. EPNet: enhancing point features with image semantics for 3d object detection[C]∥Computer Vision-ECCV 2020, Glasgow, UK, 2020: 35-52. |
| [23] | Jiao Y, Jie Z Q, Chen S X, et al. MSMDFusion: fusing LiDAR and camera at multiple scales with multi-depth seeds for 3D object detection[C]∥2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, Canada,2023: 21643-21652. |
| [24] | Liu Z W, Cheng J R, Fan J, et al. Multi-modal fusion based on depth adaptive mechanism for 3D object detection[J].IEEE Transactions on Multimedia, 2025,27: 707-717. |
| [25] | Zhang Y N, Chen J X, Huang D. CAT-Det: contrastively augmented transformer for multimodal 3D object detection[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, USA, 2022: 898-907. |
| [26] | Liao B C, Chen S Y, Wang X G, et al. MapTR: structured modeling and learning for online vectorized HD map construction[C]∥International Conference on Learning Representations, Kigali, Rwanda, 2023: 1-18. |
| [27] | Liu Z J, Tang H T, Amini A, et al. BEVFusion: multi-task multi-sensor fusion with unified bird's-eye view representation[C]∥IEEE International Conference on Robotics and Automation, London, United Kingdom,2023: 2774-2781. |
| [28] | Li Z Q, Wang W H, Li H Y, et al. BEVFormer: learning Bird's-Eye-View representation from multi-camera images via spatiotemporal transformers[C]∥Computer Vision-ECCV 2022, Tel Aviv, Israel,2022:1-18. |
| [29] | Yang L, Yu K C, Tang T,et al. BEVHeight: a robust framework for vision-based roadside 3D object detection[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, Canada, 2023: 21611-21620. |
| [30] | Geiger A, Lenz P, Urtasun R. Are we ready for autonomous driving? The KITTI Vision Benchmark Suite[C]∥IEEE Conference on Computer Vision and Pattern Recognition, Providence, USA, 2012: 3354-3361. |
| [31] | Caesar H, Bankiti V, Lang A H,et al. nuScenes: a multimodal dataset for autonomous driving[C]∥2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition(CVPR), Seattle, USA,2020: 11618-11628. |
| [32] | Lang A H, Vora S, Caesar H, et al. PointPillars: fast encoders for object detection from point clouds[C]∥2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, USA 2019: 12689-12697. |
| [33] | Shi S S, Wang X G, Li H S. PointRCNN: 3D object proposal generation and detection from point cloud[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, USA 2019: 770-779. |
| [34] | Xu S Q, Zhou D F, Fang J, et al. FusionPainting: multimodal fusion with adaptive attention for 3D object detection[C]∥IEEE International Intelligent Transportation Systems Conference, Indianapolis, USA,2021: 3047-3054. |
| [35] | Liu Z, Huang T T, Li B L, et al. EPNet++: Cascade Bi-directional fusion for multi-modal 3D object detection[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2023,45(7): 8324-8341. |
| [36] | Song Z Y, Zhang G X, Xie J, et al. VoxelNextFusion: a simple, unified, and effective voxel fusion framework for multimodal 3-D object detection[J]. IEEE Transactions on Geoscience and Remote Sensing, 2023, 61: 1-12. |
| [37] | Huang J J, Huang G, Zhu Z, et al. BEVDet: high-performance multi-camera 3D object detection in bird-eye-view[J]. arXiv, 2021: abs/2112.11790. |
| [38] | Yin T W, Zhou X Y, Krahenbuhl P. Center-Based 3D object detection and tracking[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, USA, 2021: 11784-11793. |
| [39] | Yoo J H, Kim Y, Kim J, et al. 3D-CVF: Generating joint camera and LiDAR features using cross-view spatial feature fusion for 3D object detection[C]∥Computer Vision-ECCV 2020, Glasgow,UK, 2020: 720-736. |
| [40] | Bai X Y, Hu Z Y, Zhu X G, et al. TransFusion: robust LiDAR-camera fusion for 3D object detection with transformers[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, USA, 2022: 1080-1089. |
| [41] | Xie E Z, Yu Z D, Zhou D Q, et al. M2 BEV: multi-camera joint 3D detection and segmentation with unified birds-eye view representation[J/OL]. [2024-10-22]. . |
| [42] | Yin T W, Zhou X Y, Krahenbuhl P. Multimodal virtual point 3D detection[C]∥Neural Information Processing Systems, 2021: 16494-16507. |
| [43] | Chen Z H, Li Z Y, Zhang S Q, et al. AutoAlign: Pixel-Instance feature aggregation for multimodal 3D object detection[C]∥International Joint Conference on Artificial Intelligence, Vienna, Austria, 2022:827-833. |
| [44] | Chen X Y, Zhang T Y, Wang Y, et al. FUTR3D: a unified sensor fusion framework for 3D detection[C]∥IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, Vancouver, Canada, 2023: 172-181. |
| [1] | 江晟,路启,夏淼磊,王稼禹. 基于特征融合注意力的RGB-D语义分割算法[J]. 吉林大学学报(工学版), 2026, 56(9): 2435-2443. |
| [2] | 郭洪艳,谢鸿楠,孟庆瑜. 单车智能条件下综合车辆运动状态的轨迹预测方法[J]. 吉林大学学报(工学版), 2026, 56(10): 2535-2545. |
| [3] | 才华,郑延阳,付强,王晟宇,王伟刚,马智勇. 基于多尺度候选融合与优化的三维目标检测算法[J]. 吉林大学学报(工学版), 2025, 55(2): 709-721. |
| [4] | 程鑫,刘升贤,周经美,周洲,赵祥模. 融合密集连接和高斯距离的三维目标检测算法[J]. 吉林大学学报(工学版), 2024, 54(12): 3589-3600. |
| [5] | 吕卫,韩镓泽,褚晶辉,井佩光. 基于多模态自注意力网络的视频记忆度预测[J]. 吉林大学学报(工学版), 2023, 53(4): 1211-1219. |
| [6] | 陶博,颜伏伍,尹智帅,武冬梅. 基于高精度地图增强的三维目标检测算法[J]. 吉林大学学报(工学版), 2023, 53(3): 802-809. |
|
||